python抓取网页图片示例(python爬虫)
#-*- encoding: utf-8 -*-
'''
Created on 2014-4-24
@author: Leon Wong
'''
import urllib2
import urllib
import re
import time
import os
import uuid
#获取二级页面url
def findUrl2(html):
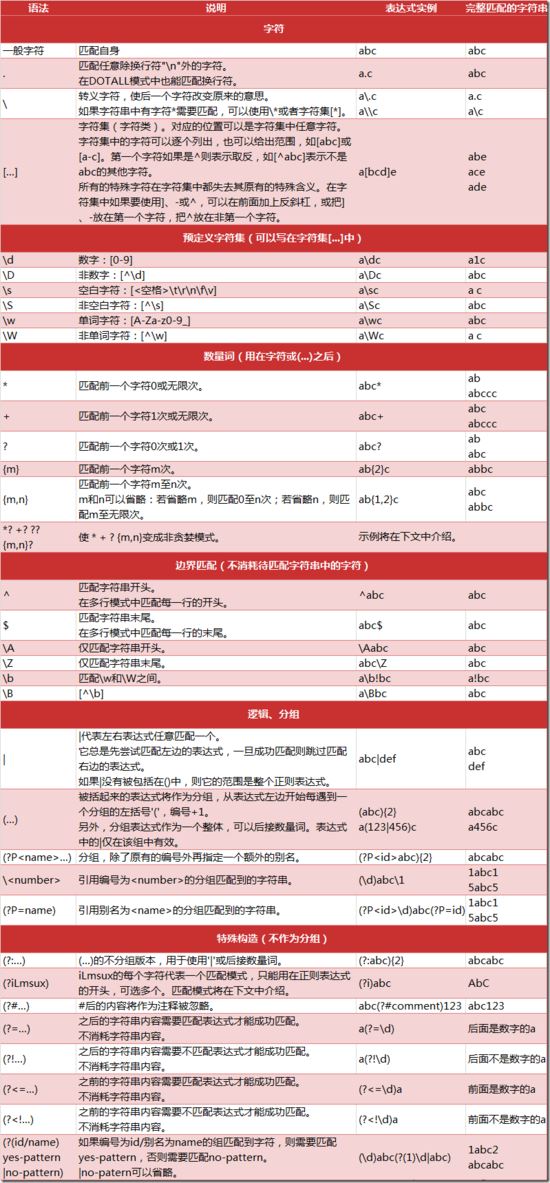
re1 = r'http://tuchong.com/\d+/\d+/|http://\w+(?<!photos).tuchong.com/\d+/'
url2list = re.findall(re1,html)
url2lstfltr = list(set(url2list))
url2lstfltr.sort(key=url2list.index)
#print url2lstfltr
return url2lstfltr
#获取html文本
def getHtml(url):
html = urllib2.urlopen(url).read().decode('utf-8')#解码为utf-8
return html
#下载图片到本地
def download(html_page , pageNo):
#定义文件夹的名字
x = time.localtime(time.time())
foldername = str(x.__getattribute__("tm_year"))+"-"+str(x.__getattribute__("tm_mon"))+"-"+str(x.__getattribute__("tm_mday"))
re2=r'http://photos.tuchong.com/.+/f/.+\.jpg'
imglist=re.findall(re2,html_page)
print imglist
download_img=None
for imgurl in imglist:
picpath = 'D:\\TuChong\\%s\\%s' % (foldername,str(pageNo))
filename = str(uuid.uuid1())
if not os.path.exists(picpath):
os.makedirs(picpath)
target = picpath+"\\%s.jpg" % filename
print "The photos location is:"+target
download_img = urllib.urlretrieve(imgurl, target)#将图片下载到指定路径中
time.sleep(1)
print(imgurl)
return download_img
# def callback(blocknum, blocksize, totalsize):
# '''回调函数
# @blocknum: 已经下载的数据块
# @blocksize: 数据块的大小
# @totalsize: 远程文件的大小
# '''
# print str(blocknum),str(blocksize),str(totalsize)
# if blocknum * blocksize >= totalsize:
# print '下载完成'
def quitit():
print "Bye!"
exit(0)
if __name__ == '__main__':
print ''' *****************************************
** Welcome to Spider for TUCHONG **
** Created on 2014-4-24 **
** @author: Leon Wong **
*****************************************'''
pageNo = raw_input("Input the page number you want to scratch (1-100),please input 'quit' if you want to quit>")
while not pageNo.isdigit() or int(pageNo) > 100 :
if pageNo == 'quit':quitit()
print "Param is invalid , please try again."
pageNo = raw_input("Input the page number you want to scratch >")
#针对图虫人像模块来爬取
html = getHtml("http://tuchong.com/tags/%E4%BA%BA%E5%83%8F/?page="+str(pageNo))
detllst = findUrl2(html)
for detail in detllst:
html2 = getHtml(detail)
download(html2,pageNo)
print "Finished."