Pytorch在NLP中的简单应用详解
因为之前在项目中一直使用Tensorflow,最近需要处理NLP问题,对Pytorch框架还比较陌生,所以特地再学习一下pytorch在自然语言处理问题中的简单使用,这里做一个记录。
一、Pytorch基础
首先,第一步是导入pytorch的一系列包
import torch
import torch.autograd as autograd #Autograd为Tensor所有操作提供自动求导方法
import torch.nn as nn
import torch.nn.functional as F
import torch.optim as optim
1)Tensor张量
a) 创建Tensors
#tensor
x = torch.Tensor([[1,2,3],[4,5,6]])
#size为2x3x4的随机数随机数
x = torch.randn((2,3,4))
b) Tensors计算
x = torch.Tensor([[1,2],[3,4]])
y = torch.Tensor([[5,6],[7,8]])
z = x+y
c) Reshape Tensors
x = torch.randn(2,3,4)
#拉直
x = x.view(-1)
#4*6维度
x = x.view(4,6)
2)计算图和自动微分
a) Variable变量
#将Tensor变为Variable
x = autograd.Variable(torch.Tensor([1,2,3]),requires_grad = True)
#将Variable变为Tensor
y = x.data
b) 反向梯度算法
x = autograd.Variable(torch.Tensor([1,2]),requires_grad=True)
y = autograd.Variable(torch.Tensor([3,4]),requires_grad=True)
z = x+y
#求和
s = z.sum()
#反向梯度传播
s.backward()
print(x.grad)
c) 线性映射
linear = nn.Linear(3,5) #三维线性映射到五维
x = autograd.Variable(torch.randn(4,3))
#输出为(4,5)维
y = linear(x)
d) 非线性映射(激活函数的使用)
x = autograd.Variable(torch.randn(5))
#relu激活函数
x_relu = F.relu(x)
print(x_relu)
x_soft = F.softmax(x)
#softmax激活函数
print(x_soft)
print(x_soft.sum())
output:
Variable containing:
-0.9347
-0.9882
 1.3801
-0.1173
 0.9317
[torch.FloatTensor of size 5]

Variable containing:
 0.0481
 0.0456
 0.4867
 0.1089
 0.3108
[torch.FloatTensor of size 5]

Variable containing:
 1
[torch.FloatTensor of size 1]

Variable containing:
-3.0350
-3.0885
-0.7201
-2.2176
-1.1686
[torch.FloatTensor of size 5]
二、Pytorch创建网络
1) word embedding词嵌入
通过nn.Embedding(m,n)实现,m表示所有的单词数目,n表示词嵌入的维度。
word_to_idx = {'hello':0,'world':1}
embeds = nn.Embedding(2,5) #即两个单词,单词的词嵌入维度为5
hello_idx = torch.LongTensor([word_to_idx['hello']])
hello_idx = autograd.Variable(hello_idx)
hello_embed = embeds(hello_idx)
print(hello_embed)
output:
Variable containing:
-0.6982 0.3909 -1.0760 -1.6215 0.4429
[torch.FloatTensor of size 1x5]
2) N-Gram 语言模型
先介绍一下N-Gram语言模型,给定一个单词序列 ,计算 ,其中 是序列的第 个单词。
import torch
import torch.nn as nn
import torch.nn.functional as F
import torch.autograd as autograd
import torch.optim as optim

from six.moves import xrange
对句子进行分词:
context_size = 2
embed_dim = 10
text_sequence = """When forty winters shall besiege thy brow,
And dig deep trenches in thy beauty's field,
Thy youth's proud livery so gazed on now,
Will be a totter'd weed of small worth held:
Then being asked, where all thy beauty lies,
Where all the treasure of thy lusty days;
To say, within thine own deep sunken eyes,
Were an all-eating shame, and thriftless praise.
How much more praise deserv'd thy beauty's use,
If thou couldst answer 'This fair child of mine
Shall sum my count, and make my old excuse,'
Proving his beauty by succession thine!
This were to be new made when thou art old,
And see thy blood warm when thou feel'st it cold.""".split()
#分词
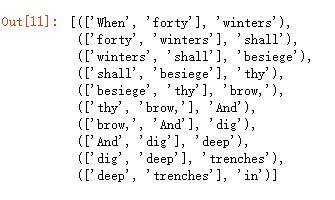
trigrams = [ ([text_sequence[i], text_sequence[i+1]], text_sequence[i+2]) for i in xrange(len(text_sequence) - 2) ]
trigrams[:10]
分词的形式为:
#建立vocab索引
vocab = set(text_sequence)
word_to_ix = {word: i for i,word in enumerate(vocab)}
建立N-Gram Language model
#N-Gram Language model
class NGramLanguageModeler(nn.Module):
 def __init__(self, vocab_size, embed_dim, context_size):
  super(NGramLanguageModeler, self).__init__()
  #词嵌入
  self.embedding = nn.Embedding(vocab_size, embed_dim)
  #两层线性分类器
  self.linear1 = nn.Linear(embed_dim*context_size, 128)
  self.linear2 = nn.Linear(128, vocab_size)

 def forward(self, input):
  embeds = self.embedding(input).view((1, -1)) #2,10拉直为20
  out = F.relu(self.linear1(embeds))
  out = F.relu(self.linear2(out))
  log_probs = F.log_softmax(out)
  return log_probs
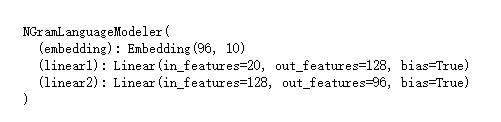
输出模型看一下网络结构
#输出模型看一下网络结构
model = NGramLanguageModeler(96,10,2)
print(model)
定义损失函数和优化器
#定义损失函数以及优化器
loss_function = nn.NLLLoss()
optimizer = optim.SGD(model.parameters(),lr = 0.01)
model = NGramLanguageModeler(len(vocab), embed_dim, context_size)
losses = []
模型训练
#模型训练
for epoch in xrange(10):
 total_loss = torch.Tensor([0])
 for context, target in trigrams:
  #1.处理数据输入为索引向量
  #print(context)
  #注:python3中map函数前要加上list()转换为列表形式
  context_idxs = list(map(lambda w: word_to_ix[w], context))
  #print(context_idxs)
  context_var = autograd.Variable( torch.LongTensor(context_idxs) )


  #2.梯度清零
  model.zero_grad()

  #3.前向传播,计算下一个单词的概率
  log_probs = model(context_var)

  #4.损失函数
  loss = loss_function(log_probs, autograd.Variable(torch.LongTensor([word_to_ix[target]])))

  #反向传播及梯度更新
  loss.backward()
  optimizer.step()

  total_loss += loss.data
 losses.append(total_loss)
print(losses)
以上这篇Pytorch在NLP中的简单应用详解就是小编分享给大家的全部内容了,希望能给大家一个参考,也希望大家多多支持【听图阁-专注于Python设计】。