python制作花瓣网美女图片爬虫
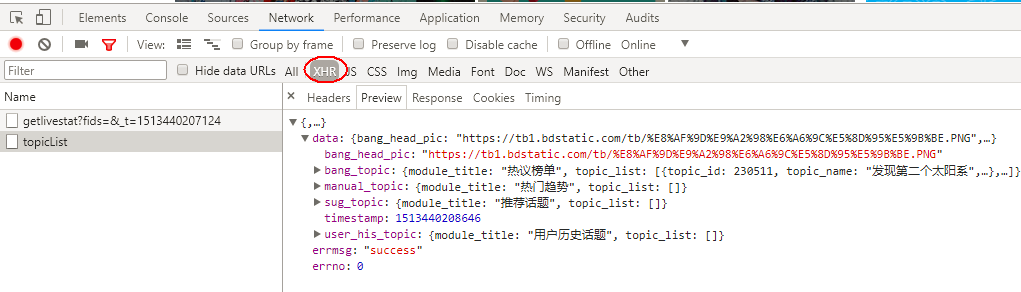
花瓣图片的加载使用了延迟加载的技术,源代码只能下载20多张图片,修改后基本能下载所有的了,只是速度有点慢,后面再优化下
import urllib, urllib2, re, sys, os,requests
path=r"C:\wqa\beautify"
url = 'http://huaban.com/favorite/beauty'
#http://huaban.com/explore/zhongwenlogo/?ig1un9tq&max=327773629&limit=20&wfl=1
i_headers = {"User-Agent": "Mozilla/5.0 (Windows NT 6.1; WOW64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/46.0.2490.71 Safari/537.36"}
count=0

def urlHandle(url):
  req = urllib2.Request(url, headers=i_headers)
  html = urllib2.urlopen(req).read()
  reg = re.compile(r'"pin_id":(\d+),.+?"file":{"farm":"farm1", "bucket":"hbimg",.+?"key":"(.*?)",.+?"type":"image/(.*?)"', re.S)
  groups = re.findall(reg, html)
  return groups

def imgHandle(groups):
  if groups:
    for att in groups:
      pin_id = att[0]
      att_url = att[1] + '_fw236'
      img_type = att[2]
      img_url = 'http://img.hb.aicdn.com/' + att_url

      r = requests.get(img_url)
      with open(path + att_url + '.' + img_type, 'wb') as fd:
        for chunk in r.iter_content():
          fd.write(chunk)

groups = urlHandle(url)
imgHandle(groups)

while(groups):
  count+=1
  print count
  pin_id = groups[-1][0]
  print pin_id
  urltemp = url+'/?max=' + str(pin_id) + '&limit=' + str(20) + '&wfl=1'
  print(urltemp)
  groups = urlHandle(urltemp)
  #print groups
  imgHandle(groups)